Request a demo
Having trouble seeing the form? Open the form here
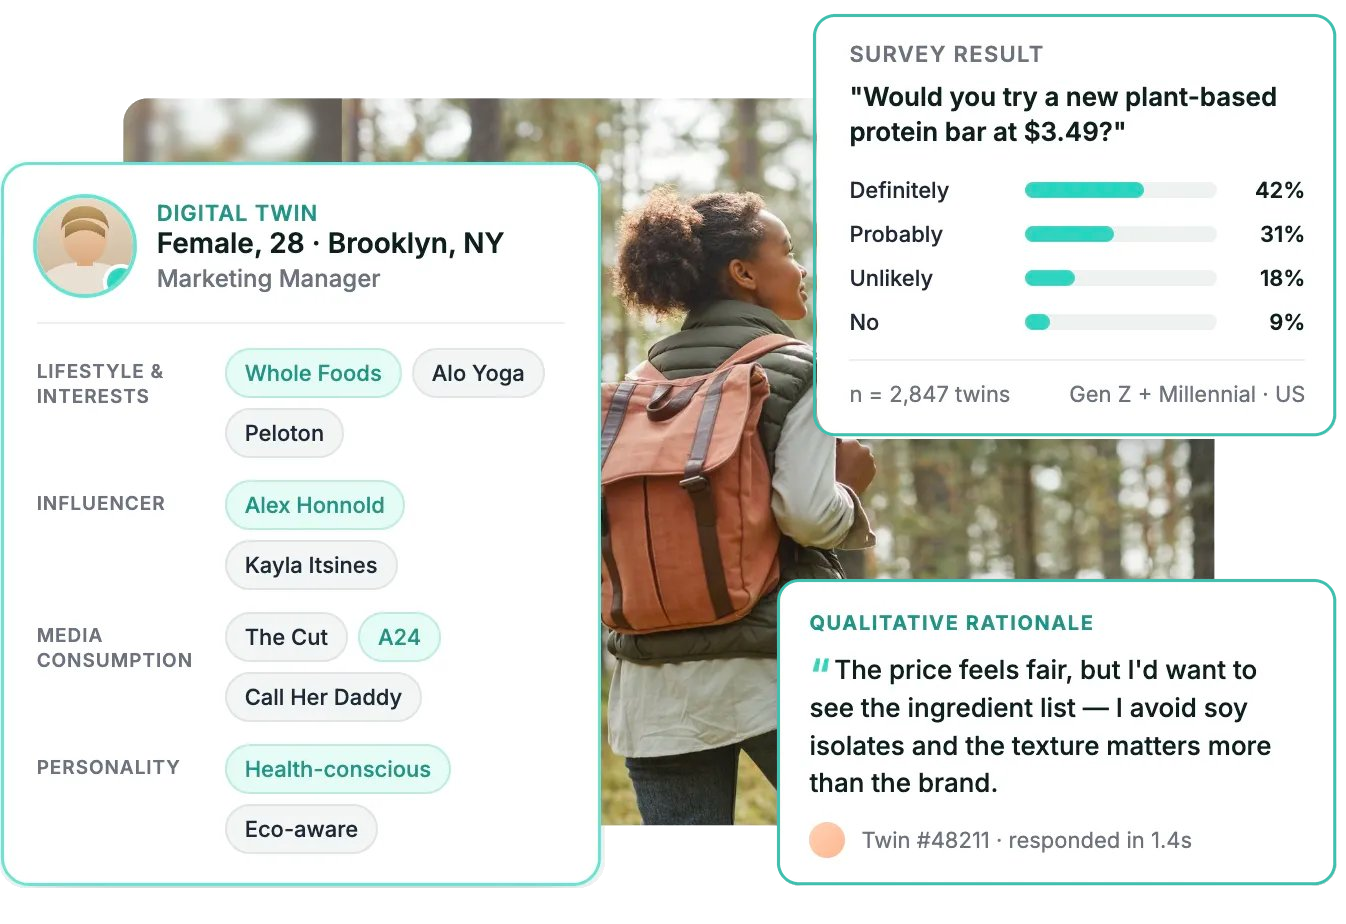
StatSocial Digital Twins are AI survey respondents built from the observed anonymized behavior of 150M+ U.S. adults, so you can run market research and pre-campaign studies against any audience you can describe, without recruiting a single person.
No recruiting · No scheduling · 3.3 pts MAE vs. published benchmarks
Having trouble seeing the form? Open the form here
Every use case runs on the same engine. StatSocial works as a single AI insights platform for consumer research, audience research, and qualitative work: field a study at scale, then open a focus group when a result deserves a conversation.
Understand what drives purchase, switching, and loyalty in a category, grounded in what your consumers actually do rather than what they recall doing.
Confirm who your audience is, what they care about, and where their attention already sits before you commit budget to reaching them.
Moderate a live session with your exact audience. Ask, probe, and redirect the discussion as it unfolds, with every quote traceable to the Twin behind it.
Put concepts, ads, and positioning in front of your market and see which version moves the segments that matter, before the media spend.
Gauge demand for new products, test pricing sensitivity, and prioritize features before committing resources.
Find the channels, publishers, and creators a specific cohort already follows, then validate the fit before you sign anything.
Define your audience by observed behavior, brand affinity, media consumption, or your own customer file. StatSocial generates the matching Digital Twins from the real signals of 150M+ U.S. adults.
Our research team designs the survey with you, then fields it to your twins. Quantitative results come back indexed to a general population baseline.
The same twins move into a live session, where you can probe a surprising result, push a segment on its reasoning, or split the room on a disagreement.
Every session ends with the full transcript and the reasoning behind each position, traceable to the part of the audience that held it.
Three ways to get answers from your target audience, and where each one breaks down.
Request a demo| Traditional panels and research firms | DIY LLM and generative AI research | StatSocial | |
|---|---|---|---|
Who answers |
Opt-in respondents sourced by a recruiter | Personas generated from model training data and demographic proxies | Digital Twins built from the observed behavior of 150M+ real U.S. adults |
| Time to results | 3 to 6 weeks | Hours | Hours |
| Hard-to-reach audiences | Low incidence means long screening and quota compromises | Available in name, but averages toward the general population | Defined from real observed behavior, including B2B, fan, creator, and niche audiences |
| Representativeness | Whoever agreed to show up | Unweighted or weighted to census proxies | Every voice weighted to the share of real buyers it represents |
| Accuracy validation | 5 to 6 pts MAE typical for opt-in panels | Rarely published | 3.3 pts MAE across 40+ Pew, Gallup, and Nielsen benchmarks |
| Qualitative follow up | Separate recruit, separate field | A new prompt with no continuity | Live AI focus groups on the same audience, mid study |
| Focus group voice risk | High. One participant can steer the group | Low, but so is real disagreement | Low. Disagreement is preserved and weighted |
| Auditability | Topline tables and a transcript | Model output with no underlying people | Cohort, distribution, and written rationale behind every answer |
| Repeat studies | New recruit, new field | New prompt | Re-query the same audience as questions evolve |
Shepherd wanted to know whether a niche audience would pay for a new product, the kind of audience that barely exists in standard panels. So they put the question to their Twins, then dug into the reasoning behind each answer.
Liked the concept, but cooled off once the conversation turned to price.
Liked the idea more than expected, just not enough to pay for it yet.
The most willing to pay, especially when the product felt creator-driven.
There isn’t a big delta between how they’re responding as a Twin and how we’re seeing them show up in real life.
Everything teams usually ask before they get started.